
Recent headlines have been filled with accusations that artificial intelligence firm OpenAI may have used mathematicians’ unpublished work to produce solutions to long-standing high-profile mathematical problems. The mathematicians had been using OpenAI’s tools in developing their own work on proofs for the Navier–Stokes fluid dynamics equations, and claim that the company – without authorisation – incorporated that work to train the AI model that came up with the proposed solution. OpenAI denies knowingly using user data for training in this case. The lack of transparency from AI companies about how their models are trained, and their record of somewhat loose interpretations of intellectual property and copyright law, have created an atmosphere of suspicion that companies will need to work hard to escape.
The dispute highlights various problems around how AI is being incorporated into research, and the use and ownership of data that AI tools interact with, and the attribution of any resultant discoveries. Data is the lifeblood of an AI model: the better the source data, the more effective the model can be, and therefore the more valuable it is for training.
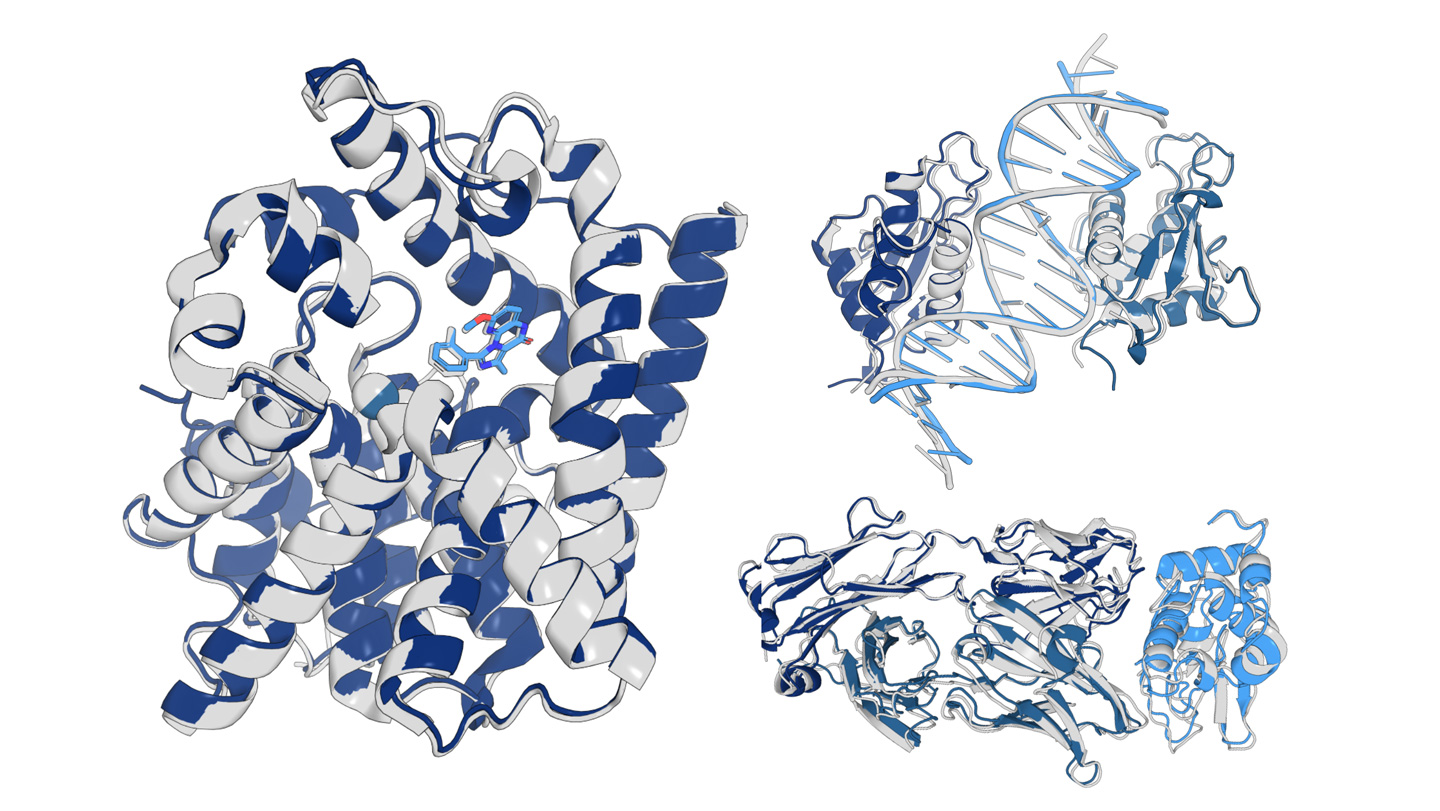
In pharmaceuticals research, one of the most significant recent uses of AI has been predicting protein structures. Google DeepMind’s AlphaFold revolutionised our ability to predict a protein’s fold from its amino acid sequence, winning its creators a share in the 2024 chemistry Nobel prize. But it has limitations – because it is mostly based on data from the public Protein Data Bank, its training set includes relatively few structures of proteins interacting with drug-like molecules, and even fewer that describe protein–protein interactions.
These interactions can drastically alter the shapes of proteins, and those shape changes are strongly linked to proteins’ functions, so understanding them is invaluable in drug development. Many pharmaceutical companies therefore maintain their own private libraries of such ligand-bound protein structures. A recent collaboration between multiple companies shows – unsurprisingly – that training an AI on each company’s individual library data produces slightly better results, but aggregating the model’s training enables the resultant AI to make significantly better structure predictions. And that benefit can be achieved without sharing the companies’ proprietary structural data.
While exploiting the data that already exists in pharmaceutical companies’ private vaults is a good start, there are still significant ‘blind spots’ in the available data. To produce even bigger improvements in AI models’ performance will require targeted generation of new datasets that fill in those gaps. That will undoubtedly require huge amounts of human ingenuity, since many of the required structures fall into classes that are difficult to capture experimentally. While we may all ultimately benefit from feeding AI’s voracious appetite for more and better data, we need to build an attribution framework that ensures we can verify that the human inputs involved are appropriately recognised and respected.